[Blog] <Optimal Solutions in the Era of Inference> Best Fit Proposal by Applied × MSI using NVIDIA MGX

アプライド
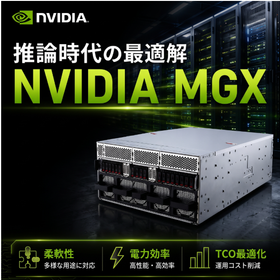
As the practical application of LLMs (large language models) like ChatGPT rapidly advances, the requirements for AI infrastructure are also undergoing significant changes. In the past, during the AI development phase, particularly in the "training" phase, the mainstream approach was to gather the highest-performing GPUs and invest heavily in data centers to pursue the speed and capacity of GPU memory. However, as models are completed and we transition to the "inference" phase, where they are utilized in actual business operations and services, new challenges are emerging. One such challenge is the issue that "using the top-tier systems for training (like DGX or HGX) for inference is often over-specification, leading to excessive initial investments and running costs." What is now required from inference infrastructure is not just "maximum performance," but rather "flexibility" and "power efficiency" tailored to specific applications. This time, we will explain the "NVIDIA MGX" architecture, which optimizes the TCO (total cost of ownership) of data centers and enables a streamlined inference foundation, along with the best-fit server configurations proposed by Applied.