
NVIDIA H200 NVL 4GPU AI server


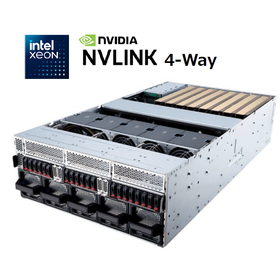
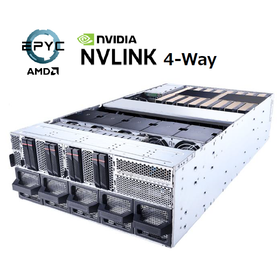
H200-equipped server that accelerates large-scale AI/HPC with NVLink 4-Way.
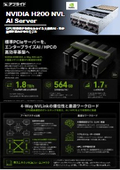
This is an AI/HPC server equipped with four NVIDIA H200 NVL GPUs, supporting high-speed communication between GPUs via NVLink Bridge. While based on a standard PCIe server, it minimizes communication bottlenecks between GPUs, efficiently handling large language model inference, generative AI, real-time analytics, and scientific computing. Each GPU is equipped with a large 141GB HBM3e memory, allowing a total of 564GB of GPU memory across four GPUs. It offers Xeon 6 models and EPYC models, and can be customized to suit various applications and existing environments.
basic information
【Xeon 6 Model】 OS: Linux/Windows CPU: Intel Xeon 6730P×2 Memory: 512GB ECC R-DIMM Storage: U.2 NVMe SSD 1.92TB GPU: NVIDIA H200 NVL 141GB×4, NVLink Bridge Board 4-way Passive×2 Power Supply: Redundant 3+1 3,200W/200V 3-year send-back warranty. 【EPYC Model】 OS: Linux CPU: AMD EPYC 9455 Memory: 512GB ECC R-DIMM Storage: U.2 NVMe SSD 1.92TB GPU: NVIDIA H200 NVL 141GB×4, same NVLink configuration Power Supply: Redundant 3+1 3,200W/200V 3-year send-back warranty.
Price range
Delivery Time
Applications/Examples of results
It is suitable for inference of large-scale language models (LLMs), generative AI applications, RAG (Retrieval-Augmented Generation), search-augmented generation, real-time data analysis, HPC simulations, CAE, CFD, molecular dynamics, drug discovery, biotechnology, and research and development purposes. The 4-Way NVLink enables high-speed communication between GPUs, making it effective for large models and high-capacity data processing that span multiple GPUs. It can be utilized as a high-performance AI server that is easy to implement based on PCIe, in universities and research institutions, research and development departments of manufacturing industries, AI service development companies, and for building AI infrastructure in data centers.
catalog(6)
Download All Catalogs
News about this product(8)
-
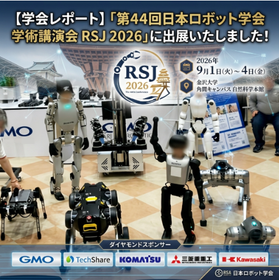
[Conference Report] "We exhibited at the 44th Annual Conference of the Robotics Society of Japan, RSJ 2026!"
Applied Corporation exhibited at the "44th Annual Conference of the Robotics Society of Japan (RSJ 2026)" held at Kanazawa University from September 1 to 4, 2026. At the venue, numerous cutting-edge robotic technologies were showcased, including AI-equipped autonomous patrol robots and industrial humanoid robots, reflecting a high level of interest in physical AI and local LLMs. At our booth, we displayed the MSI "EdgeXpert," an OEM product of NVIDIA DGX Spark, and the next-generation AI workstation "XpertStation WS300" equipped with the NVIDIA GB300 Grace Blackwell Ultra Desktop Superchip. We received many inquiries regarding the GPU and computing resources necessary for AI inference and robot development. At Applied, we offer AI servers and GPU workstations tailored to various applications, from AI learning uses such as VLM/VLA to Sim2Real simulations utilizing Isaac Sim. If you are considering building a next-generation R&D environment using physical AI, please feel free to consult with us.
-
[Blog] <Optimal Solutions in the Era of Inference> Best Fit Proposal by Applied × MSI using NVIDIA MGX
As the practical application of LLMs (large language models) like ChatGPT rapidly advances, the requirements for AI infrastructure are also undergoing significant changes. In the past, during the AI development phase, particularly in the "training" phase, the mainstream approach was to gather the highest-performing GPUs and invest heavily in data centers to pursue the speed and capacity of GPU memory. However, as models are completed and we transition to the "inference" phase, where they are utilized in actual business operations and services, new challenges are emerging. One such challenge is the issue that "using the top-tier systems for training (like DGX or HGX) for inference is often over-specification, leading to excessive initial investments and running costs." What is now required from inference infrastructure is not just "maximum performance," but rather "flexibility" and "power efficiency" tailored to specific applications. This time, we will explain the "NVIDIA MGX" architecture, which optimizes the TCO (total cost of ownership) of data centers and enables a streamlined inference foundation, along with the best-fit server configurations proposed by Applied.
-

[Blog] "The Possibilities of Automotive Development Expanding with LS-DYNA × AI" HPC Supporting Next-Generation CAE
In automotive development, CAE (Computer Aided Engineering) is widely used to enhance safety and performance. Among these, "crash analysis," which predicts the deformation, stress, and strain of the vehicle body during a collision, is crucial in the field of crash safety. The representative CAE software LS-DYNA allows for the setting of conditions such as body shape, materials, thickness, and collision speed to analyze the behavior during a crash. On the other hand, automotive development requires not just a single design proposal but also the comparison of numerous candidates, including materials, thickness, component shapes, and reinforcement positions. This is where the focus shifts to utilizing the analysis data accumulated in LS-DYNA to train AI, which can be used for predicting analysis results and screening design candidates. Rather than replacing CAE, combining CAE with AI has the potential to make the design review process more efficient. Furthermore, HPC (High Performance Computing) becomes essential as a foundation supporting CAE analysis, AI learning, and large-scale data processing.
-
[Blog] Generative AI is moving from "answering" to "acting." Starting with agent-type AI using NVIDIA Nemotron.
With the spread of generative AI, including ChatGPT, AI has begun to be utilized in various scenarios such as text generation, summarization, translation, and programming assistance. On the other hand, in corporate and research and development settings, there is an increasing expectation for more advanced AI applications, not just to answer questions, but to: - Automatically search for necessary information from internal technical documents - Compare multiple pieces of information to determine the next course of action - Operate external tools and business systems - Progress through a series of tasks including research, analysis, code generation, and report creation This system, which infers based on objectives and utilizes necessary information and tools to advance tasks, is referred to as "Agentic AI." Supporting this Agentic AI is NVIDIA's open model family, known as NVIDIA Nemotron. In this article, we will introduce what NVIDIA Nemotron is, how it differs from traditional generative AI, and what applications can be considered in manufacturing and research and development.
-
[Blog] An Explanation of Changes in Data Centers and New Options
In recent years, have you noticed the changes in data centers? The needs for data centers are currently fluctuating significantly due to the explosive spread of AI. This time, we will introduce the changes in data centers in the IT industry, which can be seen as a reflection of the trends of the times.
Recommended products







Distributors

Applied Corporation is a computer manufacturing company based in Hakata-ku, Fukuoka City, Fukuoka Prefecture, with 65 locations nationwide. We provide the latest business proposals, from cutting-edge computers to the implementation of DX and solutions, for corporate clients across the country.