
NVIDIA HGX B300 8GPU AI Server


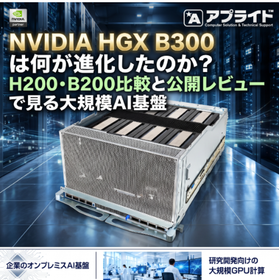
Over 2TB of GPU memory × high-speed NVLink! Accelerating large-scale LLM inference and generative AI development.
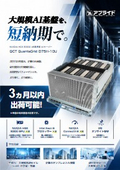
The NVIDIA HGX B300 is a high-performance GPU platform designed for large-scale AI and generative AI development, equipped with eight Blackwell Ultra GPUs. It features a large capacity of 270GB of HBM3e memory per GPU, totaling 2,160GB across all eight GPUs, and supports high-speed communication between GPUs via the fifth-generation NVLink/NVSwitch. It assists in processing tasks that require large memory and high computational performance, such as inference for large language models (LLMs), long document retrieval-augmented generation (RAG), AI agents, and multimodal AI. Applied offers an 8-GPU server based on the QCT "QuantaGrid D75H-10U" featuring the HGX B300. With an air-cooled 10U rack-mounted configuration, it can accommodate a wide range of needs from AI research and development to building large-scale AI infrastructure within enterprises. Implementation can be discussed for as short as approximately three months.
basic information
【QCT QuantaGrid D75H-10U Configuration Example】 ■GPU: NVIDIA HGX B300 (Blackwell Ultra GPU x8) ■GPU Memory: 270GB HBM3e x8 (Total 2,160GB) ■GPU Memory Bandwidth: Up to 7.7TB/s (Nominal value per GPU) ■Inter-GPU Communication: 5th Generation NVLink/NVSwitch (Up to 1.8TB/s per GPU) ■CPU: Intel Xeon 6788P x2 (86 cores/172 threads each) ■Memory: 128GB/2TB configuration example ■Storage: M.2 SSD 1.92TB x2 ■Network: NVIDIA ConnectX-8 x8, 800Gb/s Ethernet/InfiniBand compatible ■Chassis: 10U rack-mounted, air-cooled ■Maintenance: 3 years on-site maintenance *Configuration, specifications, and delivery times may vary based on implementation conditions.
Price range
Delivery Time
Applications/Examples of results
【Large-Scale LLM and Generative AI Development】 Can be utilized for inference, evaluation, and additional training of LLMs that consume a large amount of GPU memory, starting with large MoE models like DeepSeek-R1. 【In-House RAG and AI Agents】 Supports systems that require high inference processing capabilities for searching and summarizing long technical documents, utilizing internal knowledge, and simultaneous AI usage by multiple users. 【Image AI and Multimodal Analysis】 Suitable for research and development of VLMs (Visual Language Models), image recognition AI, and AI models that combine images and text, as well as for additional training. 【AI Infrastructure for Research Institutions and Enterprises】 Can be used for building on-premises AI infrastructure in universities, research institutions, manufacturing industries, and AI development companies. It also supports large model processing with multiple GPUs and scaling to multiple servers.
catalog(5)
Download All Catalogs
Recommended products





Distributors

Applied Corporation is a computer manufacturing company based in Hakata-ku, Fukuoka City, Fukuoka Prefecture, with 65 locations nationwide. We provide the latest business proposals, from cutting-edge computers to the implementation of DX and solutions, for corporate clients across the country.